函数调用 | OpenAI API
来源: https://developers.openai.com/api/docs/guides/function-calling 抓取时间: 2026-07-21 16:18:48
函数调用(也称为工具调用)为 OpenAI 模型提供了一种强大而灵活的方式,使其能够与外部系统连接并访问训练数据之外的数据。本指南展示了如何将模型连接到应用程序提供的数据和操作。我们将展示如何使用函数工具(由 JSON 模式定义)和自定义工具(使用自由文本输入和输出)。
如果您的应用程序有许多函数或大型模式,您可以将函数调用与工具搜索配对,以延迟很少使用的工具并仅在模型需要时加载它们。只有 gpt-5.4 及更高版本的模型支持 tool_search。
工作原理
让我们首先了解关于工具调用的几个关键术语。在我们有了工具调用的共享词汇之后,我们将通过一些实际示例向您展示它是如何完成的。
工具 - 我们提供给模型的功能
函数或工具在抽象上指的是我们告诉模型可以访问的一段功能。当模型生成对提示的响应时,它可能会决定需要工具提供的数据或功能来遵循提示的指令。
您可以让模型访问以下工具:
- 获取某个位置的今天天气
- 访问给定用户 ID 的账户详细信息
- 为丢失的订单退款
或者您希望模型在响应提示时能够知道或做的任何其他事情。
当我们向模型发出带有提示的 API 请求时,我们可以包含模型可以考虑使用的工具列表。例如,如果我们希望模型能够回答关于世界某个地方当前天气的问题,我们可能会让它访问一个以 location 作为参数的 get_weather 工具。
工具调用 - 模型使用工具的请求
函数调用或工具调用指的是我们可以从模型获得的一种特殊响应,如果它检查提示,然后确定为了遵循提示中的指令,它需要调用我们提供给它的其中一个工具。
如果模型在 API 请求中收到类似“巴黎今天的天气如何?”的提示,它可以用 get_weather 工具的工具调用响应,以 Paris 作为 location 参数。
工具调用输出 - 我们为模型生成的输出
函数调用输出或工具调用输出指的是工具使用来自模型工具调用的输入生成的响应。工具调用输出可以是结构化 JSON 或纯文本,并且应该包含对特定模型工具调用的引用(在接下来的示例中由 call_id 引用)。为了完成我们的天气示例:
- 模型可以访问以
location作为参数的get_weather工具。 - 响应类似“巴黎今天的天气如何?”的提示时,模型返回一个工具调用,其中包含一个值为
Paris的location参数。 - 工具调用输出可能返回一个 JSON 对象(例如,
{\"temperature\": \"25\", \"unit\": \"C\"},表示当前温度为 25 度)、图像内容或文件内容。
然后我们将所有工具定义、原始提示、模型的工具调用和工具调用输出发送回模型,最终收到如下文本响应:
巴黎今天的天气是 25°C。
函数与工具
- 函数是一种特定类型的工具,由 JSON 模式定义。函数定义允许模型将数据传递给您的应用程序,您的代码可以在其中访问数据或采取模型建议的操作。
- 除了函数工具,还有自定义工具(本指南中描述),它们使用自由文本输入和输出工作。
- 还有作为 OpenAI 平台一部分的内置工具。这些工具使模型能够搜索网络、执行代码、访问远程 MCP服务器的功能等等。
工具调用流程
工具调用是您的应用程序通过 OpenAI API 与模型之间的多步骤对话。工具调用流程有五个高级步骤:
- 使用模型可以调用的工具向模型发出请求
- 从模型接收工具调用
- 使用工具调用的输入在应用程序端执行代码
- 使用工具输出向模型发出第二个请求
- 从模型接收最终响应(或更多工具调用)
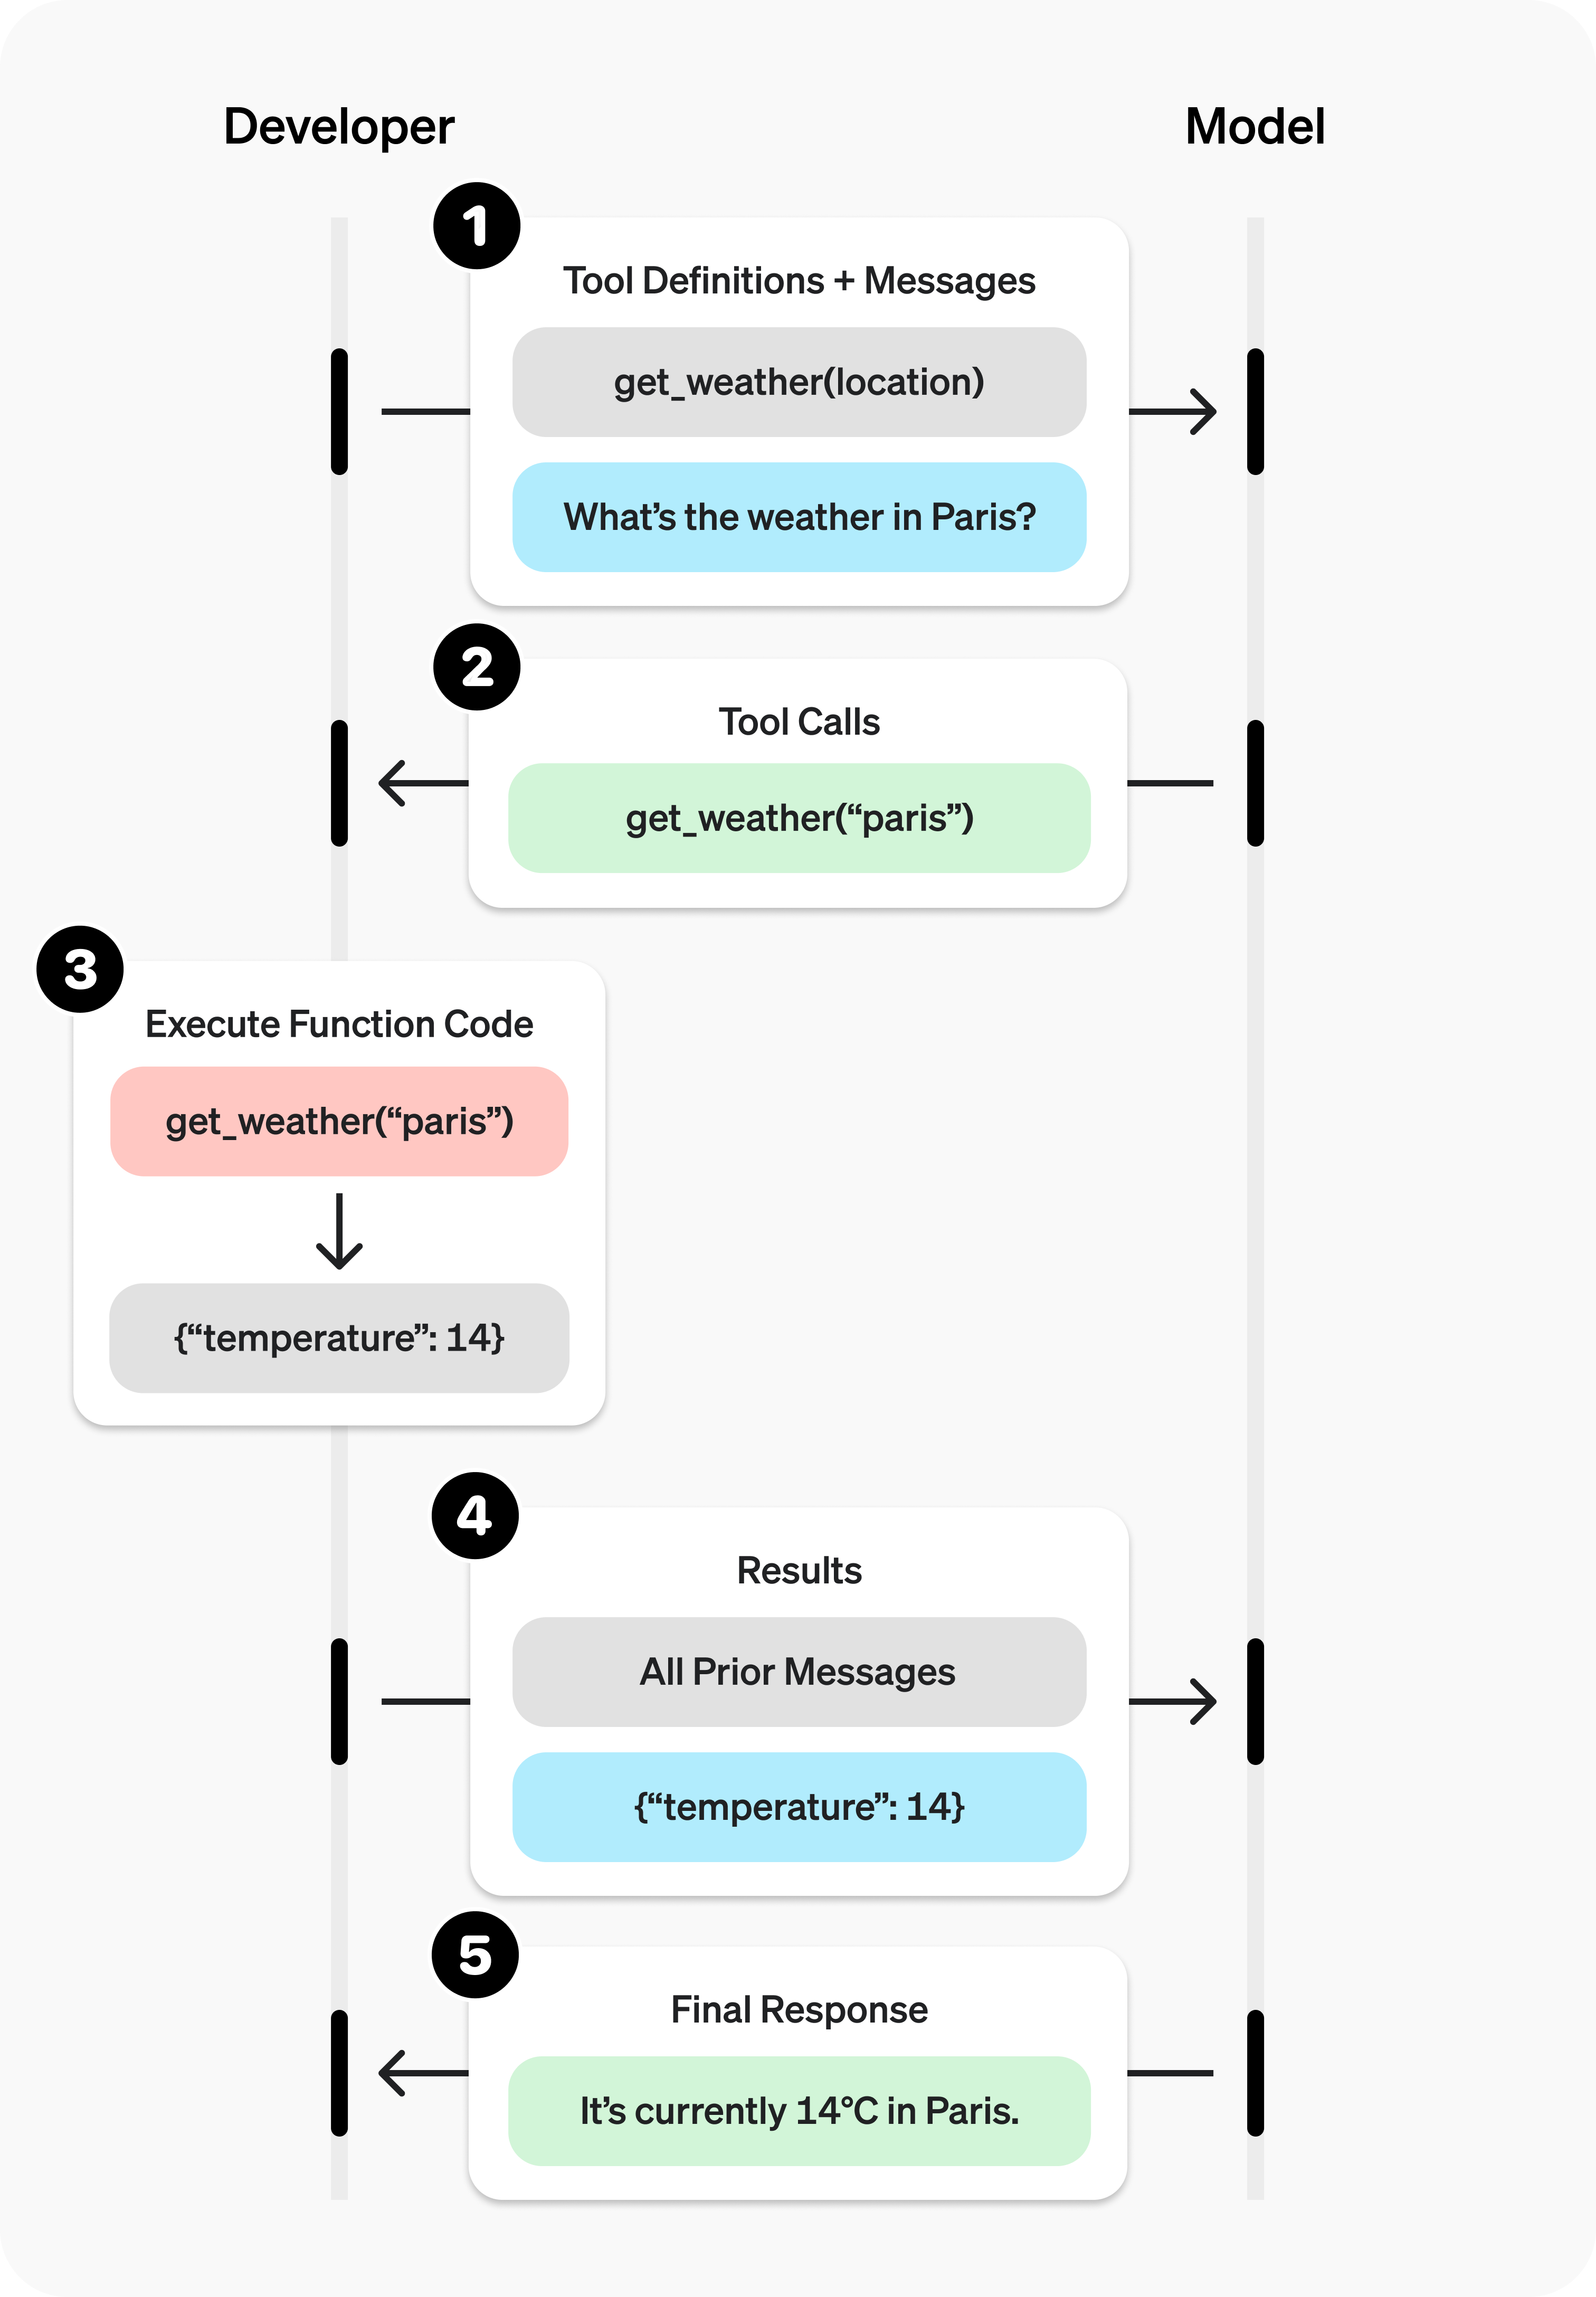
使用 Responses,您的应用程序可以继续此流程,直到任务所需的所有工具调用完成。如果您需要一个框架来包装该循环周围的重复编排,请参阅Responses API 与 Agents SDK 的比较。
函数工具示例
让我们看一个 get_horoscope 函数的端到端工具调用流程,该函数获取星座的每日运势。
Chat Completions 完整工具调用示例
from openai import OpenAI
import json

client = OpenAI()

# 1. 为模型定义可调用工具列表
tools = [
    {
        "type": "function",
        "function": {
            "name": "get_horoscope",
            "description": "Get today's horoscope for an astrological sign.",
            "parameters": {
                "type": "object",
                "properties": {
                    "sign": {
                        "type": "string",
                        "description": "An astrological sign like Taurus or Aquarius",
                    },
                },
                "required": ["sign"],
                "additionalProperties": False,
            },
            "strict": True,
        },
    },
]

def get_horoscope(sign):
    return f"{sign}: Next Tuesday you will befriend a baby otter."

messages = [
    {"role": "user", "content": "What is my horoscope? I am an Aquarius."}
]

# 2. 使用定义的工具提示模型
response = client.chat.completions.create(
    model="gpt-5.6",
    messages=messages,
    tools=tools,
)

messages.append(response.choices[0].message)

for tool_call in response.choices[0].message.tool_calls or []:
    if tool_call.function.name == "get_horoscope":
        # 3. 执行 get_horoscope 的函数逻辑
        args = json.loads(tool_call.function.arguments)
        horoscope = get_horoscope(args["sign"])

        # 4. 向模型提供函数调用结果
        messages.append(
            {
                "role": "tool",
                "tool_call_id": tool_call.id,
                "content": json.dumps({"horoscope": horoscope}),
            }
        )

response = client.chat.completions.create(
    model="gpt-5.6",
    messages=messages,
    tools=tools,
)

# 5. 模型应该能够给出响应!
print(response.choices[0].message.content)
import OpenAI from "openai";

const openai = new OpenAI();

// 1. 为模型定义可调用工具列表
/** @type {OpenAI.ChatCompletionTool[]} */
const tools = [
  {
    type: "function",
    function: {
      name: "get_horoscope",
      description: "Get today's horoscope for an astrological sign.",
      parameters: {
        type: "object",
        properties: {
          sign: {
            type: "string",
            description: "An astrological sign like Taurus or Aquarius",
          },
        },
        required: ["sign"],
        additionalProperties: false,
      },
      strict: true,
    },
  },
];

function getHoroscope(sign) {
  return `${sign}: Next Tuesday you will befriend a baby otter.`;
}

/** @type {OpenAI.ChatCompletionMessageParam[]} */
const messages = [
  { role: "user", content: "What is my horoscope? I am an Aquarius." },
];

// 2. 使用定义的工具提示模型
let response = await openai.chat.completions.create({
  model: "gpt-5.6",
  messages,
  tools,
});

messages.push(response.choices[0].message);

for (const toolCall of response.choices[0].message.tool_calls ?? []) {
  if (toolCall.type !== "function") continue;

  if (toolCall.function.name === "get_horoscope") {
    // 3. 执行 get_horoscope 的函数逻辑
    const args = JSON.parse(toolCall.function.arguments);
    const horoscope = getHoroscope(args.sign);

    // 4. 向模型提供函数调用结果
    messages.push({
      role: "tool",
      tool_call_id: toolCall.id,
      content: JSON.stringify({ horoscope }),
    });
  }
}

response = await openai.chat.completions.create({
  model: "gpt-5.6",
  messages,
  tools,
});

// 5. 模型应该能够给出响应!
console.log(response.choices[0].message.content);
Responses 完整工具调用示例
from openai import OpenAI
import json

client = OpenAI()

# 1. 为模型定义可调用工具列表
tools = [
    {
        "type": "function",
        "name": "get_horoscope",
        "description": "Get today's horoscope for an astrological sign.",
        "parameters": {
            "type": "object",
            "properties": {
                "sign": {
                    "type": "string",
                    "description": "An astrological sign like Taurus or Aquarius",
                },
            },
            "required": ["sign"],
        },
    },
]

def get_horoscope(sign):
    return f"{sign}: Next Tuesday you will befriend a baby otter."

# 创建我们将随时间添加的运行输入列表
input_list = [
    {"role": "user", "content": "What is my horoscope? I am an Aquarius."}
]

# 2. 使用定义的工具提示模型
response = client.responses.create(
    model="gpt-5.6",
    tools=tools,
    input=input_list,
)

# 保存后续请求的函数调用输出
input_list += response.output

for item in response.output:
    if item.type == "function_call":
        if item.name == "get_horoscope":
            # 3. 执行 get_horoscope 的函数逻辑
            sign = json.loads(item.arguments)["sign"]
            horoscope = get_horoscope(sign)

            # 4. 向模型提供函数调用结果
            input_list.append({
                "type": "function_call_output",
                "call_id": item.call_id,
                "output": horoscope,
            })

print("Final input:")
print(input_list)

response = client.responses.create(
    model="gpt-5.6",
    instructions="Respond only with a horoscope generated by a tool.",
    tools=tools,
    input=input_list,
)

# 5. 模型应该能够给出响应!
print("Final output:")
print(response.model_dump_json(indent=2))
print("\n" + response.output_text)
import OpenAI from "openai";

const openai = new OpenAI();

// 1. 为模型定义可调用工具列表
/** @type {OpenAI.Responses.Tool[]} */
const tools = [
  {
    type: "function",
    name: "get_horoscope",
    description: "Get today's horoscope for an astrological sign.",
    parameters: {
      type: "object",
      properties: {
        sign: {
          type: "string",
          description: "An astrological sign like Taurus or Aquarius",
        },
      },
      required: ["sign"],
      additionalProperties: false,
    },
    strict: true,
  },
];

function getHoroscope(sign) {
  return `${sign}: Next Tuesday you will befriend a baby otter.`;
}

// 创建我们将随时间添加的运行输入列表
/** @type {OpenAI.Responses.ResponseInput} */
let input = [
  { role: "user", content: "What is my horoscope? I am an Aquarius." },
];

// 2. 使用定义的工具提示模型
let response = await openai.responses.create({
  model: "gpt-5.6",
  tools,
  input,
});

// 为下一轮保留模型输出
input.push(...response.output);

for (const item of response.output) {
  if (item.type !== "function_call") continue;

  if (item.name === "get_horoscope") {
    // 3. 执行 get_horoscope 的函数逻辑
    const { sign } = JSON.parse(item.arguments);
    const horoscope = getHoroscope(sign);

    // 4. 向模型提供函数调用结果
    input.push({
      type: "function_call_output",
      call_id: item.call_id,
      output: horoscope,
    });
  }
}

console.log("Final input:");
console.log(JSON.stringify(input, null, 2));

response = await openai.responses.create({
  model: "gpt-5.6",
  instructions: "Respond only with a horoscope generated by a tool.",
  tools,
  input,
});

// 5. 模型应该能够给出响应!
console.log("Final output:");
console.log(response.output_text);
请注意,对于像 GPT-5 或 o4-mini 这样的推理模型,模型响应中返回的任何带有工具调用的推理项目也必须与工具调用输出一起传递回来。
定义函数
函数通常在每个 API 请求的 tools 参数中声明。使用工具搜索,您的应用程序还可以在交互稍后加载延迟函数。无论哪种方式,每个可调用函数都使用相同的模式形状。函数定义具有以下属性:
| 字段 | 描述 |
|---|---|
type | 这应该始终是 function |
name | 函数的名称(例如 get_weather) |
description | 关于何时以及如何使用该函数的详细信息 |
parameters | 定义函数输入参数的 JSON 模式 |
strict | 是否为函数调用强制执行严格模式 |
以下是 get_weather 函数的示例函数定义:
{
  "type": "function",
  "name": "get_weather",
  "description": "Retrieves current weather for the given location.",
  "parameters": {
    "type": "object",
    "properties": {
      "location": {
        "type": "string",
        "description": "City and country e.g. Bogotá, Colombia"
      },
      "units": {
        "type": "string",
        "enum": ["celsius", "fahrenheit"],
        "description": "Units the temperature will be returned in."
      }
    },
    "required": ["location", "units"],
    "additionalProperties": false
  },
  "strict": true
}
因为 parameters 由 JSON 模式定义,您可以利用其许多丰富功能,如属性类型、枚举、描述、嵌套对象和递归对象。
定义命名空间
使用命名空间按域对相关工具进行分组,例如 crm、billing 或 shipping。命名空间有助于组织类似工具,当模型必须在服务于不同系统或目的的工具之间进行选择时特别有用,例如一个搜索工具用于您的 CRM,另一个用于您的支持票务系统。
{
  "type": "namespace",
  "name": "crm",
  "description": "CRM tools for customer lookup and order management.",
  "tools": [
    {
      "type": "function",
      "name": "get_customer_profile",
      "description": "Fetch a customer profile by customer ID.",
      "parameters": {
        "type": "object",
        "properties": {
          "customer_id": { "type": "string" }
        },
        "required": ["customer_id"],
        "additionalProperties": false
      }
    },
    {
      "type": "function",
      "name": "list_open_orders",
      "description": "List open orders for a customer ID.",
      "defer_loading": true,
      "parameters": {
        "type": "object",
        "properties": {
          "customer_id": { "type": "string" }
        },
        "required": ["customer_id"],
        "additionalProperties": false
      }
    }
  ]
}
工具搜索
如果您需要让模型访问大型工具生态系统,您可以使用 tool_search 延迟加载部分或全部这些工具。tool_search 工具允许模型搜索相关工具,将它们添加到模型上下文中,然后使用它们。只有 gpt-5.4 及更高版本的模型支持它。阅读工具搜索指南了解更多信息。
##(可选)使用 pydantic 和 zod 进行函数调用
虽然我们鼓励您直接定义函数模式,但我们的 SDK 有帮助程序可以将 pydantic 和 zod 对象转换为模式。并非所有 pydantic 和 zod 功能都受支持。
定义对象来表示函数模式
from openai import OpenAI, pydantic_function_tool
from pydantic import BaseModel, Field

client = OpenAI()

class GetWeather(BaseModel):
    location: str = Field(
        ...,
        description="City and country e.g. Bogotá, Colombia"
    )

tools = [pydantic_function_tool(GetWeather)]

completion = client.chat.completions.create(
    model="gpt-5.6",
    messages=[{"role": "user", "content": "What's the weather like in Paris today?"}],
    tools=tools
)

print(completion.choices[0].message.tool_calls)
import OpenAI from "openai";
import { z } from "zod";
import { zodFunction } from "openai/helpers/zod";

const openai = new OpenAI();

const GetWeatherParameters = z.object({
  location: z.string().describe("City and country e.g. Bogotá, Colombia"),
});

const tools = [
  zodFunction({ name: "getWeather", parameters: GetWeatherParameters }),
];

/** @type {OpenAI.ChatCompletionMessageParam[]} */
const messages = [
  { role: "user", content: "What's the weather like in Paris today?" },
];

const response = await openai.chat.completions.create({
  model: "gpt-5.6",
  messages,
  tools,
  store: true,
});

console.log(response.choices[0].message.tool_calls);
定义函数的最佳实践
- 编写清晰详细的函数名称、参数描述和指令。
- 明确描述函数的目的和每个参数(及其格式),以及输出代表什么。
- **使用系统提示描述何时(以及何时不)使用每个函数。**通常,告诉模型_确切_该做什么。
- 包括示例和边缘情况,特别是纠正任何重复出现的故障。(**注意:**添加示例可能会损害推理模型的性能。)
- **对于延迟工具,将详细指南放在函数描述中并保持命名空间描述简洁。**命名空间帮助模型选择加载什么;函数描述帮助它正确使用加载的工具。
- 应用软件工程最佳实践。
- 使函数明显且直观。(最小惊奇原则)
- 使用枚举和对象结构,使无效状态无法表示。(例如,
toggle_light(on: bool, off: bool)允许无效调用) - **通过实习生测试。**一个实习生/人类是否能正确使用该函数,只凭你给模型的东西?(如果不能,他们会问你什么问题?将答案添加到提示中。)
- 减轻模型的负担,并尽可能使用代码。
- **不要让模型填充你已经知道的参数。**例如,如果你已经根据先前的菜单有了
order_id,不要有order_id参数——改为使用无参数的submit_refund()并通过代码传递order_id。 - **合并始终按顺序调用的函数。**例如,如果你总是在
query_location()之后调用mark_location(),只需将标记逻辑移动到查询函数调用中。
- **不要让模型填充你已经知道的参数。**例如,如果你已经根据先前的菜单有了
- 保持初始可用函数的数量较小以提高准确性。
- 评估您在不同数量的函数下的性能。
- 目标是在任何时候一开始就提供少于 20 个可用函数,尽管这只是一个软建议。
- 使用工具搜索来延迟工具表面的大或不常用部分,而不是预先暴露所有内容。
- 利用 OpenAI 资源。
- 在 Playground 中生成和迭代函数模式。
- 考虑微调以提高大量函数或困难任务的函数调用准确性。(Cookbook)
令牌使用
在底层,函数以模型经过训练的语法注入到系统消息中。这意味着可调用函数定义会计入模型的上下文限制,并作为输入令牌计费。如果您遇到令牌限制,我们建议限制预先加载的函数数量,尽可能缩短描述,或使用工具搜索,以便延迟工具仅在需要时加载。
如果您在工具规范中定义了许多函数,也可以使用微调来减少使用的令牌数量。
处理函数调用
当模型调用函数时,您必须执行它并返回结果。由于模型响应可以包含零个、一个或多个调用,因此最佳实践是假设有多个。
响应有一个 tool_calls 数组,每个都有一个 id(稍后用于提交函数结果)和一个包含 name 和 JSON 编码 arguments 的 function。
Chat Completions 多个函数调用的示例响应
[
    {
        "id": "call_12345xyz",
        "type": "function",
        "function": {
            "name": "get_weather",
            "arguments": "{\"location\":\"Paris, France\"}"
        }
    },
    {
        "id": "call_67890abc",
        "type": "function",
        "function": {
            "name": "get_weather",
            "arguments": "{\"location\":\"Bogotá, Colombia\"}"
        }
    },
    {
        "id": "call_99999def",
        "type": "function",
        "function": {
            "name": "send_email",
            "arguments": "{\"to\":\"bob@email.com\",\"body\":\"Hi bob\"}"
        }
    }
]
Chat Completions 执行函数调用并追加结果
for tool_call in completion.choices[0].message.tool_calls:
    name = tool_call.function.name
    args = json.loads(tool_call.function.arguments)

    result = call_function(name, args)
    messages.append({
        "role": "tool",
        "tool_call_id": tool_call.id,
        "content": str(result)
    })
for (const toolCall of completion.choices[0].message.tool_calls ?? []) {
  if (toolCall.type !== "function") continue;

  const name = toolCall.function.name;
  const args = JSON.parse(toolCall.function.arguments);

  const result = await callFunction(name, args);
  messages.push({
    role: "tool",
    tool_call_id: toolCall.id,
    content: result.toString(),
  });
}
Responses 响应的 output 数组包含一个 type 值为 function_call 的条目。每个条目都有 call_id(稍后用于提交函数结果)、name 和 JSON 编码的 arguments。
Responses 多个函数调用的示例响应
[
    {
        "id": "fc_12345xyz",
        "call_id": "call_12345xyz",
        "type": "function_call",
        "name": "get_weather",
        "arguments": "{\"location\":\"Paris, France\"}"
    },
    {
        "id": "fc_67890abc",
        "call_id": "call_67890abc",
        "type": "function_call",
        "name": "get_weather",
        "arguments": "{\"location\":\"Bogotá, Colombia\"}"
    },
    {
        "id": "fc_99999def",
        "call_id": "call_99999def",
        "type": "function_call",
        "name": "send_email",
        "arguments": "{\"to\":\"bob@email.com\",\"body\":\"Hi bob\"}"
    }
]
如果您正在使用工具搜索,您可能还会在 function_call 之前看到 tool_search_call 和 tool_search_output 项目。一旦函数加载完毕,以与此处显示的相同方式处理函数调用。
Responses 执行函数调用并追加结果
for tool_call in response.output:
    if tool_call.type != "function_call":
        continue

    name = tool_call.name
    args = json.loads(tool_call.arguments)

    result = call_function(name, args)
    input_messages.append({
        "type": "function_call_output",
        "call_id": tool_call.call_id,
        "output": str(result)
    })
for (const toolCall of response.output) {
  if (toolCall.type !== "function_call") {
    continue;
  }

  const name = toolCall.name;
  const args = JSON.parse(toolCall.arguments);

  const result = await callFunction(name, args);
  input.push({
    type: "function_call_output",
    call_id: toolCall.call_id,
    output: result.toString(),
  });
}
在上面的示例中,我们有一个假设的 call_function 来路由每个调用。以下是一个可能的实现:
Responses 执行函数调用并追加结果
def call_function(name, args):
    if name == "get_weather":
        return get_weather(**args)
    if name == "send_email":
        return send_email(**args)
const callFunction = async (name, args) => {
  if (name === "get_weather") {
    return getWeather(args.latitude, args.longitude);
  }
  if (name === "send_email") {
    return sendEmail(args.to, args.body);
  }
};
格式化结果
您在 function_call_output 消息中传递的结果通常应该是字符串,格式由您决定(JSON、错误代码、纯文本等)。模型将根据需要解释该字符串。
对于返回图像或文件的函数,您可以传递图像或文件对象数组而不是字符串。
如果您的函数没有返回值(例如 send_email),只需返回一个指示成功或失败的字符串。(例如,"success")
将结果合并到响应中
将结果追加到您的 messages 后,您可以将它们发送回模型以获得最终响应。
Chat Completions 将结果发送回模型
completion = client.chat.completions.create(
    model="gpt-5.6",
    messages=messages,
    tools=tools,
)
const completion = await openai.chat.completions.create({
  model: "gpt-5.6",
  messages,
  tools,
  store: true,
});
将结果追加到您的 input 后,您可以将它们发送回模型以获得最终响应。
Responses 将结果发送回模型
response = client.responses.create(
    model="gpt-5.6",
    input=input_messages,
    tools=tools,
)
const response = await openai.responses.create({
  model: "gpt-5.6",
  input,
  tools,
});
最终响应
"It's about 15°C in Paris, 18°C in Bogotá, and I've sent that email to Bob."
其他配置
工具选择
默认情况下,模型将确定何时以及使用多少工具。您可以使用 tool_choice 参数强制特定行为。
- 自动:(默认)调用零个、一个或多个函数。
tool_choice: "auto" - **必需:**调用一个或多个函数。
tool_choice: "required" - **强制函数:**调用 exactly 一个特定函数。
tool_choice: {\"type\": \"function\", \"name\": \"get_weather\"} - **允许的工具:**将模型可以进行的工具调用限制为模型可用工具的子集。
何时使用 allowed_tools
如果您希望只使工具的子集跨模型请求可用,但不修改您传递的工具列表,以便您可以最大化来自提示缓存的节省,您可能希望配置 allowed_tools 列表。
"tool_choice": {
    "type": "allowed_tools",
    "mode": "auto",
    "tools": [
        { "type": "function", "name": "get_weather" },
        { "type": "function", "name": "search_docs" }
    ]
  }
}
您还可以将 tool_choice 设置为 "none" 来模仿不传递任何函数的行为。
当您使用工具搜索时,tool_choice 仍然适用于当前轮次中可调用的工具。这在您加载工具子集后并希望将模型限制到该子集时最有用。
并行函数调用
使用内置工具时,并行函数调用是不可能的。
模型可能选择在单个轮次中调用多个函数。您可以通过将 parallel_tool_calls 设置为 false 来防止这种情况,这确保只调用零个或一个工具。
**注意:**目前,如果您使用的是微调模型,并且模型在一个轮次中调用多个函数,那么这些调用的严格模式将被禁用。
**关于 gpt-4.1-nano-2025-04-14 的注意事项:**如果启用了并行工具调用,gpt-4.1-nano 的此快照有时可能包含对同一工具的多个工具调用。建议在使用此 nano 快照时禁用此功能。
严格模式
将 strict 设置为 true 将确保函数调用可靠地遵循函数模式,而不是尽力而为。我们建议始终启用严格模式。
在底层,严格模式通过利用我们的结构化输出功能工作,因此引入了几个要求:
additionalProperties必须为parameters中的每个对象设置为false。properties中的所有字段必须标记为required。
您可以通过添加 null 作为 type 选项来表示可选字段(请参见下面的示例)。
如果您发送 strict: true 并且您的模式不符合上述要求,请求将被拒绝并包含有关缺少约束的详细信息。如果您省略 strict,默认取决于 API:如果可能,Responses 请求将尝试将您的模式规范化为严格模式,如果模式无法与严格模式兼容,将回退到非严格、尽力而为的函数调用。发生回退时,响应工具将显示 strict: false。Chat Completions 请求默认保持非严格。要在 Responses 中选择退出严格模式并保持非严格、尽力而为的函数调用,请显式设置 strict: false。
严格模式启用
{
    "type": "function",
    "function": {
        "name": "get_weather",
        "description": "Retrieves current weather for the given location.",
        "strict": true,
        "parameters": {
            "type": "object",
            "properties": {
                "location": {
                    "type": "string",
                    "description": "City and country e.g. Bogotá, Colombia"
                },
                "units": {
                    "type": ["string", "null"],
                    "enum": ["celsius", "fahrenheit"],
                    "description": "Units the temperature will be returned in."
                }
            },
            "required": ["location", "units"],
            "additionalProperties": false
        }
    }
}
严格模式禁用
{
    "type": "function",
    "function": {
        "name": "get_weather",
        "description": "Retrieves current weather for the given location.",
        "parameters": {
            "type": "object",
            "properties": {
                "location": {
                    "type": "string",
                    "description": "City and country e.g. Bogotá, Colombia"
                },
                "units": {
                    "type": "string",
                    "enum": ["celsius", "fahrenheit"],
                    "description": "Units the temperature will be returned in."
                }
            },
            "required": ["location"],
        }
    }
}
Responses 严格模式启用
{
    "type": "function",
    "name": "get_weather",
    "description": "Retrieves current weather for the given location.",
    "strict": true,
    "parameters": {
        "type": "object",
        "properties": {
            "location": {
                "type": "string",
                "description": "City and country e.g. Bogotá, Colombia"
            },
            "units": {
                "type": ["string", "null"],
                "enum": ["celsius", "fahrenheit"],
                "description": "Units the temperature will be returned in."
            }
        },
        "required": ["location", "units"],
        "additionalProperties": false
    }
}
Responses 严格模式禁用
{
    "type": "function",
    "name": "get_weather",
    "description": "Retrieves current weather for the given location.",
    "parameters": {
        "type": "object",
        "properties": {
            "location": {
                "type": "string",
                "description": "City and country e.g. Bogotá, Colombia"
            },
            "units": {
                "type": "string",
                "enum": ["celsius", "fahrenheit"],
                "description": "Units the temperature will be returned in."
            }
        },
        "required": ["location"],
    }
}
在 playground 中生成的所有模式都启用了严格模式。
虽然我们建议您启用严格模式,但它有一些限制:
- JSON 模式的一些功能不受支持。(请参见支持的模式。)
特别是对于微调模型:
- 模式在第一个请求上经过额外处理(然后被缓存)。如果您的模式因请求而异,这可能会导致更高的延迟。
- 模式被缓存以提高性能,并且不符合零数据保留的条件。
流式传输
流式传输可用于通过显示模型填充参数时调用的函数,甚至实时显示参数来显示进度。
流式传输函数调用与流式传输常规响应非常相似:您将 stream 设置为 true 并获取带有 delta 对象的块。
Chat Completions 流式传输函数调用
from openai import OpenAI

client = OpenAI()

tools = [{
    "type": "function",
    "function": {
        "name": "get_weather",
        "description": "Get current temperature for a given location.",
        "parameters": {
            "type": "object",
            "properties": {
                "location": {
                    "type": "string",
                    "description": "City and country e.g. Bogotá, Colombia"
                }
            },
            "required": ["location"],
            "additionalProperties": False
        },
        "strict": True
    }
}]

stream = client.chat.completions.create(
    model="gpt-5.6",
    messages=[{"role": "user", "content": "What's the weather like in Paris today?"}],
    tools=tools,
    stream=True
)

for chunk in stream:
    delta = chunk.choices[0].delta
    print(delta.tool_calls)
import { OpenAI } from "openai";

const openai = new OpenAI();

/** @type {OpenAI.ChatCompletionTool[]} */
const tools = [
  {
    type: "function",
    function: {
      name: "get_weather",
      description: "Get current temperature for a given location.",
      parameters: {
        type: "object",
        properties: {
          location: {
            type: "string",
            description: "City and country e.g. Bogotá, Colombia",
          },
        },
        required: ["location"],
        additionalProperties: false,
      },
      strict: true,
    },
  },
];

const stream = await openai.chat.completions.create({
  model: "gpt-5.6",
  messages: [
    { role: "user", content: "What's the weather like in Paris today?" },
  ],
  tools,
  stream: true,
  store: true,
});

for await (const chunk of stream) {
  const delta = chunk.choices[0].delta;
  console.log(delta.tool_calls);
}
输出 delta.tool_calls
[{"index": 0, "id": "call_DdmO9pD3xa9XTPNJ32zg2hcA", "function": {"arguments": "", "name": "get_weather"}, "type": "function"}]
[{"index": 0, "id": null, "function": {"arguments": "{\"", "name": null}, "type": null}]
[{"index": 0, "id": null, "function": {"arguments": "location", "name": null}, "type": null}]
[{"index": 0, "id": null, "function": {"arguments": "\":\"", "name": null}, "type": null}]
[{"index": 0, "id": null, "function": {"arguments": "Paris", "name": null}, "type": null}]
[{"index": 0, "id": null, "function": {"arguments": ",", "name": null}, "type": null}]
[{"index": 0, "id": null, "function": {"arguments": " France", "name": null}, "type": null}]
[{"index": 0, "id": null, "function": {"arguments": "\"}", "name": null}, "type": null}]
null
然而,您不是将块聚合成单个 content 字符串,而是将块聚合成编码的 arguments JSON 对象。
当模型调用一个或多个函数时,每个 delta 的 tool_calls 字段将被填充。每个 tool_call 包含以下字段:
| 字段 | 描述 |
|---|---|
index | 标识 delta 属于哪个函数调用 |
id | 工具调用 id。 |
function | 函数调用 delta(name 和 arguments) |
type | tool_call 的类型(对于函数调用始终为 function) |
其中许多字段仅在每个工具调用的第一个 delta 中设置,如 id、function.name 和 type。
以下是一个代码片段,演示如何将 delta 聚合成最终的 tool_calls 对象。
Chat Completions 累积 tool_call deltas
final_tool_calls = {}

for chunk in stream:
    for tool_call in chunk.choices[0].delta.tool_calls or []:
        index = tool_call.index

        if index not in final_tool_calls:
            final_tool_calls[index] = tool_call

        final_tool_calls[index].function.arguments += tool_call.function.arguments
const finalToolCalls = {};

for await (const chunk of stream) {
  const toolCalls = chunk.choices[0].delta.tool_calls || [];
  for (const toolCall of toolCalls) {
    const { index } = toolCall;

    if (!finalToolCalls[index]) {
      finalToolCalls[index] = toolCall;
    }

    finalToolCalls[index].function.arguments += toolCall.function.arguments;
  }
}
累积的 final_tool_calls[0]
{
    "index": 0,
    "id": "call_RzfkBpJg3zeR0S242qfvjadNe",
    "function": {
        "name": "get_weather",
        "arguments": "{\"location\":\"Paris, France\"}"
    }
}
流式传输可用于通过显示模型填充参数时调用的函数,甚至实时显示参数来显示进度。
流式传输函数调用与流式传输常规响应非常相似:您将 stream 设置为 true 并获取不同的 event 对象。
Responses 流式传输函数调用
from openai import OpenAI

client = OpenAI()

tools = [{
    "type": "function",
    "name": "get_weather",
    "description": "Get current temperature for a given location.",
    "parameters": {
        "type": "object",
        "properties": {
            "location": {
                "type": "string",
                "description": "City and country e.g. Bogotá, Colombia"
            }
        },
        "required": [
            "location"
        ],
        "additionalProperties": False
    }
}]

stream = client.responses.create(
    model="gpt-5.6",
    input=[{"role": "user", "content": "What's the weather like in Paris today?"}],
    tools=tools,
    stream=True
)

for event in stream:
    print(event)
import { OpenAI } from "openai";

const client = new OpenAI();

/** @type {OpenAI.Responses.Tool[]} */
const tools = [
  {
    type: "function",
    name: "get_weather",
    description: "Get current temperature for provided coordinates in celsius.",
    parameters: {
      type: "object",
      properties: {
        latitude: { type: "number" },
        longitude: { type: "number" },
      },
      required: ["latitude", "longitude"],
      additionalProperties: false,
    },
    strict: true,
  },
];

const stream = await openai.responses.create({
  model: "gpt-5.6",
  input: [{ role: "user", content: "What's the weather like in Paris today?" }],
  tools,
  stream: true,
  store: true,
});

for await (const event of stream) {
  console.log(event);
}
输出事件
{"type":"response.output_item.added","response_id":"resp_1234xyz","output_index":0,"item":{"type":"function_call","id":"fc_1234xyz","call_id":"call_1234xyz","name":"get_weather","arguments":""}}
{"type":"response.function_call_arguments.delta","response_id":"resp_1234xyz","item_id":"fc_1234xyz","output_index":0,"delta":"{\""}
{"type":"response.function_call_arguments.delta","response_id":"resp_1234xyz","item_id":"fc_1234xyz","output_index":0,"delta":"location"}
{"type":"response.function_call_arguments.delta","response_id":"resp_1234xyz","item_id":"fc_1234xyz","output_index":0,"delta":"\":\""}
{"type":"response.function_call_arguments.delta","response_id":"resp_1234xyz","item_id":"fc_1234xyz","output_index":0,"delta":"Paris"}
{"type":"response.function_call_arguments.delta","response_id":"resp_1234xyz","item_id":"fc_1234xyz","output_index":0,"delta":","}
{"type":"response.function_call_arguments.delta","response_id":"resp_1234xyz","item_id":"fc_1234xyz","output_index":0,"delta":" France"}
{"type":"response.function_call_arguments.delta","response_id":"resp_1234xyz","item_id":"fc_1234xyz","output_index":0,"delta":"\"}"}
{"type":"response.function_call_arguments.done","response_id":"resp_1234xyz","item_id":"fc_1234xyz","output_index":0,"arguments":"{\"location\":\"Paris, France\"}"}
{"type":"response.output_item.done","response_id":"resp_1234xyz","output_index":0,"item":{"type":"function_call","id":"fc_1234xyz","call_id":"call_1234xyz","name":"get_weather","arguments":"{\"location\":\"Paris, France\"}"}}
然而,您不是将块聚合成单个 content 字符串,而是将块聚合成编码的 arguments JSON 对象。
当模型调用一个或多个函数时,将为每个函数调用发出 type 为 response.output_item.added 的事件,其中包含以下字段:
| 字段 | 描述 |
|---|---|
response_id | 函数调用所属的响应的 id |
output_index | 响应中输出项的索引。这表示响应中的各个函数调用。 |
item | 进行中的函数调用项,包含 name、arguments 和 id 字段 |
之后,您将收到一系列 type 为 response.function_call_arguments.delta 的事件,其中包含 arguments 字段的 delta。这些事件包含以下字段:
| 字段 | 描述 |
|---|---|
response_id | 函数调用所属的响应的 id |
item_id | delta 所属的函数调用项的 id |
output_index | 响应中输出项的索引。这表示响应中的各个函数调用。 |
delta | arguments 字段的 delta。 |
以下是一个代码片段,演示如何将 delta 聚合成最终的 tool_call 对象。
Responses 累积 tool_call deltas
final_tool_calls = {}

for event in stream:
    if event.type === 'response.output_item.added':
        final_tool_calls[event.output_index] = event.item;
    elif event.type === 'response.function_call_arguments.delta':
        index = event.output_index

        if final_tool_calls[index]:
            final_tool_calls[index].arguments += event.delta
const finalToolCalls = {};

for await (const event of stream) {
  if (event.type === "response.output_item.added") {
    finalToolCalls[event.output_index] = event.item;
  } else if (event.type === "response.function_call_arguments.delta") {
    const index = event.output_index;

    if (finalToolCalls[index]) {
      finalToolCalls[index].arguments += event.delta;
    }
  }
}
累积的 final_tool_calls[0]
{
    "type": "function_call",
    "id": "fc_1234xyz",
    "call_id": "call_2345abc",
    "name": "get_weather",
    "arguments": "{\"location\":\"Paris, France\"}"
}
当模型完成调用函数时,将发出 type 为 response.function_call_arguments.done 的事件。此事件包含整个函数调用,包括以下字段:
| 字段 | 描述 |
|---|---|
response_id | 函数调用所属的响应的 id |
output_index | 响应中输出项的索引。这表示响应中的各个函数调用。 |
item | 函数调用项,包含 name、arguments 和 id 字段。 |
自定义工具
自定义工具的工作方式与 JSON 模式驱动的函数工具非常相似。但不是向模型提供工具所需输入的显式指令,模型可以将任意字符串作为输入传递回您的工具。这对于避免不必要地将响应包装在 JSON 中,或对响应应用自定义语法非常有用(下文将详细介绍)。
以下代码示例显示创建一个自定义工具,该工具期望接收包含 Python 代码的文本字符串作为响应。
自定义工具调用示例
from openai import OpenAI

client = OpenAI()

response = client.responses.create(
    model="gpt-5.6",
    input="Use the code_exec tool to print hello world to the console.",
    tools=[
        {
            "type": "custom",
            "name": "code_exec",
            "description": "Executes arbitrary Python code.",
        }
    ]
)
print(response.output)
import OpenAI from "openai";
const client = new OpenAI();

const response = await client.responses.create({
  model: "gpt-5.6",
  input: "Use the code_exec tool to print hello world to the console.",
  tools: [
    {
      type: "custom",
      name: "code_exec",
      description: "Executes arbitrary Python code.",
    },
  ],
});

console.log(response.output);
与之前一样,output 数组将包含模型生成的工具调用。除了这次,工具调用输入以纯文本形式给出。
[
  {
    "id": "rs_6890e972fa7c819ca8bc561526b989170694874912ae0ea6",
    "type": "reasoning",
    "content": [],
    "summary": []
  },
  {
    "id": "ctc_6890e9753e8819c9338825b3e1994810694874912ae0ea6",
    "type": "custom_tool_call",
    "status": "completed",
    "call_id": "call_pmlLjmvG33KJdyVdC4MVdk5N",
    "input": "print(\"hello world\")",
    "name": "code_exec"
  }
]
上下文无关语法
上下文无关语法(CFG)是一组规则,定义如何以给定格式生成有效文本。对于自定义工具,您可以提供一个 CFG,该 CFG 将约束模型对自定义工具的文本输入。
您可以在配置自定义工具时使用 grammar 参数提供自定义 CFG。目前,我们在定义语法时支持两种 CFG 语法:lark 和 regex。
Lark CFG
Lark 上下文无关语法示例
from openai import OpenAI

client = OpenAI()

grammar = """
start: expr
expr: term (SP ADD SP term)* -> add
| term
term: factor (SP MUL SP factor)* -> mul
| factor
factor: INT
SP: " "
ADD: "+"
MUL: "*"
%import common.INT
"""

response = client.responses.create(
    model="gpt-5.6",
    input="Use the math_exp tool to add four plus four.",
    tools=[
        {
            "type": "custom",
            "name": "math_exp",
            "description": "Creates valid mathematical expressions",
            "format": {
                "type": "grammar",
                "syntax": "lark",
                "definition": grammar,
            },
        }
    ]
)
print(response.output)
import OpenAI from "openai";
const client = new OpenAI();

const grammar = `
start: expr
expr: term (SP ADD SP term)* -> add
| term
term: factor (SP MUL SP factor)* -> mul
| factor
factor: INT
SP: " "
ADD: "+"
MUL: "*"
%import common.INT
`;

const response = await client.responses.create({
  model: "gpt-5.6",
  input: "Use the math_exp tool to add four plus four.",
  tools: [
    {
      type: "custom",
      name: "math_exp",
      description: "Creates valid mathematical expressions",
      format: {
        type: "grammar",
        syntax: "lark",
        definition: grammar,
      },
    },
  ],
});

console.log(response.output);
然后工具的输出应该符合您定义的 Lark CFG:
[
  {
    "id": "rs_6890ed2b6374819dbbff5353e6664ef103f4db9842be4829",
    "type": "reasoning",
    "content": [],
    "summary": []
  },
  {
    "id": "ctc_6890ed2f32e8819daa62bef77393b1a40d7962f622d1c260",
    "type": "custom_tool_call",
    "status": "completed",
    "call_id": "call_8m4XCnYvEmFlzHgDHbaOCFlK",
    "input": "4 + 4",
    "name": "math_exp"
  }
]
语法是使用 Lark 的变体指定的。模型采样使用 LLGuidance 约束。Lark 的某些功能不受支持:
- 词法分析器正则表达式中的环视
- 词法分析器正则表达式中的惰性修饰符(
*?,+?,??) - 终结符的优先级
- 模板
- 导入(除了内置的
%import公共) %declares
我们建议使用 Lark IDE 来试验自定义语法。
保持语法简单
尽量使您的语法尽可能简单。如果语法过于复杂,OpenAI API 可能会返回错误,因此您应该确保在 API 中使用您期望的语法之前,它是兼容的。
Lark 语法可能很难完善。虽然简单的语法性能最可靠,但复杂的语法通常需要对语法定义本身、提示和工具描述进行迭代,以确保模型不会偏离分布。
正确与不正确的模式
正确(单个有界终结符):
start: SENTENCE
SENTENCE: /[A-Za-z, ]*(the hero|a dragon|an old man|the princess)[A-Za-z, ]*(fought|saved|found|lost)[A-Za-z, ]*(a treasure|the kingdom|a secret|his way)[A-Za-z, ]*\./
不要这样做(跨规则/终结符拆分)。这尝试让规则在终结符之间划分自由文本。词法分析器将贪婪地匹配自由文本片段,您将失去控制:
start: sentence
sentence: /[A-Za-z, ]+/ subject /[A-Za-z, ]+/ verb /[A-Za-z, ]+/ object /[A-Za-z, ]+/
小写规则不影响终结符如何从输入中切分——只有终结符定义会。当您需要“锚点之间的任何文本”时,将其作为一个巨型正则表达式终结符,以便词法分析器准确匹配一次并具有您想要的结构。
终结符与规则
Lark 对词法分析器令牌使用终结符(按照惯例,大写),对解析器产生式使用规则(按照惯例,小写)。保持在受支持的子集内并避免意外的最实际方法是保持语法简单明确,并使用具有明确关注点分离的终结符和规则。
终结符使用的正则表达式语法是 Rust regex crate 语法,而不是 Python 的 re 模块。
关键思想和最佳实践
词法分析器在解析器之前运行
在应用任何 CFG 规则逻辑之前,词法分析器匹配终结符(贪婪地 / 最长匹配优先)。如果您尝试通过拆分跨多个规则的方式“塑造”一个终结符,词法分析器无法由这些规则指导——只能由终结符正则表达式指导。
当您从自由格式跨度中雕刻文本时,优先使用单个终结符
如果您需要识别嵌入在任意文本中的模式(例如,带有“锚点之间的任何内容”的自然语言),将其表达为单个终结符。不要尝试将自由文本终结符与解析器规则交错;贪婪的词法分析器不会尊重您预期的边界,并且模型很可能会偏离分布。
使用规则组合离散令牌
当您将明确定界的终结符(数字、关键字、标点符号)组合成更大的结构时,规则是理想的。它们不是约束两个终结符之间“内容”的正确工具。
保持终结符简单、有界且自包含
倾向于显式字符类和有界量词({0,10},而不是到处无界的 *)。如果您需要“直到句号的任何文本”,更喜欢像 /[^.\n]{0,10}*\./ 这样的表达式,而不是 /.+\./ 以避免失控的增长。
使用规则组合令牌,而不是指导正则表达式内部
良好的规则用法示例:
start: expr
NUMBER: /[0-9]+/
PLUS: "+"
MINUS: "-"
expr: term (("+"|"-") term)*
term: NUMBER
明确处理空白
不要依赖开放式的 %ignore 指令。使用无界忽略指令可能导致语法过于复杂和/或可能导致模型偏离分布。更喜欢在允许空白的地方穿线显式终结符。
故障排除
- 如果 API 因为语法过于复杂而拒绝它,请简化规则和终结符,并删除无界的
%ignore。 - 如果自定义工具使用意外令牌调用,请确认终结符没有重叠;检查贪婪词法分析器。
- 当模型偏离“分布外”时(表现为模型产生过长或重复的输出,语法正确但语义错误):
- 收紧语法。
- 迭代提示(添加少样本示例)和工具描述(解释语法并指示模型推理并遵守它)。
- 尝试更高的推理努力(例如,从中等提升到高)。
正则表达式 CFG
正则表达式上下文无关语法示例
from openai import OpenAI

client = OpenAI()

grammar = r"^(?P<month>January|February|March|April|May|June|July|August|September|October|November|December)\s+(?P<day>\d{1,2})(?:st|nd|rd|th)?\s+(?P<year>\d{4})\s+at\s+(?P<hour>0?[1-9]|1[0-2])(?P<ampm>AM|PM)$"

response = client.responses.create(
    model="gpt-5.6",
    input="Use the timestamp tool to save a timestamp for August 7th 2025 at 10AM.",
    tools=[
        {
            "type": "custom",
            "name": "timestamp",
            "description": "Saves a timestamp in date + time in 24-hr format.",
            "format": {
                "type": "grammar",
                "syntax": "regex",
                "definition": grammar,
            },
        }
    ]
)
print(response.output)
import OpenAI from "openai";
const client = new OpenAI();

const grammar =
  "^(?P<month>January|February|March|April|May|June|July|August|September|October|November|December)\\s+(?P<day>\\d{1,2})(?:st|nd|rd|th)?\\s+(?P<year>\\d{4})\\s+at\\s+(?P<hour>0?[1-9]|1[0-2])(?P<ampm>AM|PM)$";

const response = await client.responses.create({
  model: "gpt-5.6",
  input:
    "Use the timestamp tool to save a timestamp for August 7th 2025 at 10AM.",
  tools: [
    {
      type: "custom",
      name: "timestamp",
      description: "Saves a timestamp in date + time in 24-hr format.",
      format: {
        type: "grammar",
        syntax: "regex",
        definition: grammar,
      },
    },
  ],
});

console.log(response.output);
然后工具的输出应该符合您定义的 Regex CFG:
[
  {
    "id": "rs_6894f7a3dd4c81a1823a723a00bfa8710d7962f622d1c260",
    "type": "reasoning",
    "content": [],
    "summary": []
  },
  {
    "id": "ctc_6894f7ad7fb881a1bffa1f377393b1a40d7962f622d1c260",
    "type": "custom_tool_call",
    "status": "completed",
    "call_id": "call_8m4XCnYvEmFlzHgDHbaOCFlK",
    "input": "August 7th 2025 at 10AM",
    "name": "timestamp"
  }
]
与 Lark 语法一样,正则表达式使用 Rust regex crate 语法,而不是 Python 的 re 模块。
正则表达式的某些功能不受支持:
- 环视
- 惰性修饰符(
*?,+?,??)
关键思想和最佳实践
模式必须在一行上
如果您需要匹配输入中的换行符,请使用转义序列 \n。不要使用冗长/扩展模式,该模式允许模式跨多行。
将正则表达式作为纯模式字符串提供
不要将模式括在 // 中。